The problem
Journey maps drove Tovuti's product discovery, but building one meant weeks of hand synthesis. The evidence existed — help articles, demo transcripts, support tickets, internal notes — scattered across systems, in formats built for reading, not for structuring. A ticket that says "confusing" does not say which step confused anyone, for which persona, at what stage. Every discovery cycle paid that synthesis tax again: 10–15 hours per cycle, and the resulting map was a static deliverable that started rotting the day it shipped.
The obvious fixes fail in predictable ways. A generic AI chat can summarize sources, but it produces prose, not a structured artifact a team can edit, version, and hand off. And skipping synthesis altogether means designing from the loudest recent complaint rather than the actual pattern. The gap was a tool purpose-built for the research-to-artifact pipeline.
Architecture
JEM is a five-stage pipeline: ingest sources, scope the map through a guided AI conversation, generate a structured draft, edit it on an interactive canvas, and keep it versioned in a library. I designed the product end to end — the flow, the interfaces, and the underlying data model (Map → Tabs → Personas → Cells → Steps and Frictions) — and it was built on Tovuti's existing stack (Nuxt 3 + Vue 3, Tailwind, Pinia, Cloudflare D1 + R2, the Claude API) with the platform's lead engineer implementing and the principal engineer reviewing infrastructure. Staying on the house stack was a deliberate call: design-system components could be reused directly, and streaming responses made the scoping chat feel like a conversation instead of a batch job.
Steps:
- Source ingestion — Paste, upload, or link raw material. Every source gets a type — help article, transcript, support ticket, KB guide, notes — so the model knows what kind of evidence it is reading, and error states catch format problems before they poison a generation.
- Guided scoping chat — A streaming Claude conversation narrows what the map should cover before anything is generated. Directional refinement buttons — "make it more tactical," "focus on one persona," "include error recovery" — steer scope without requiring prompt-writing skill.
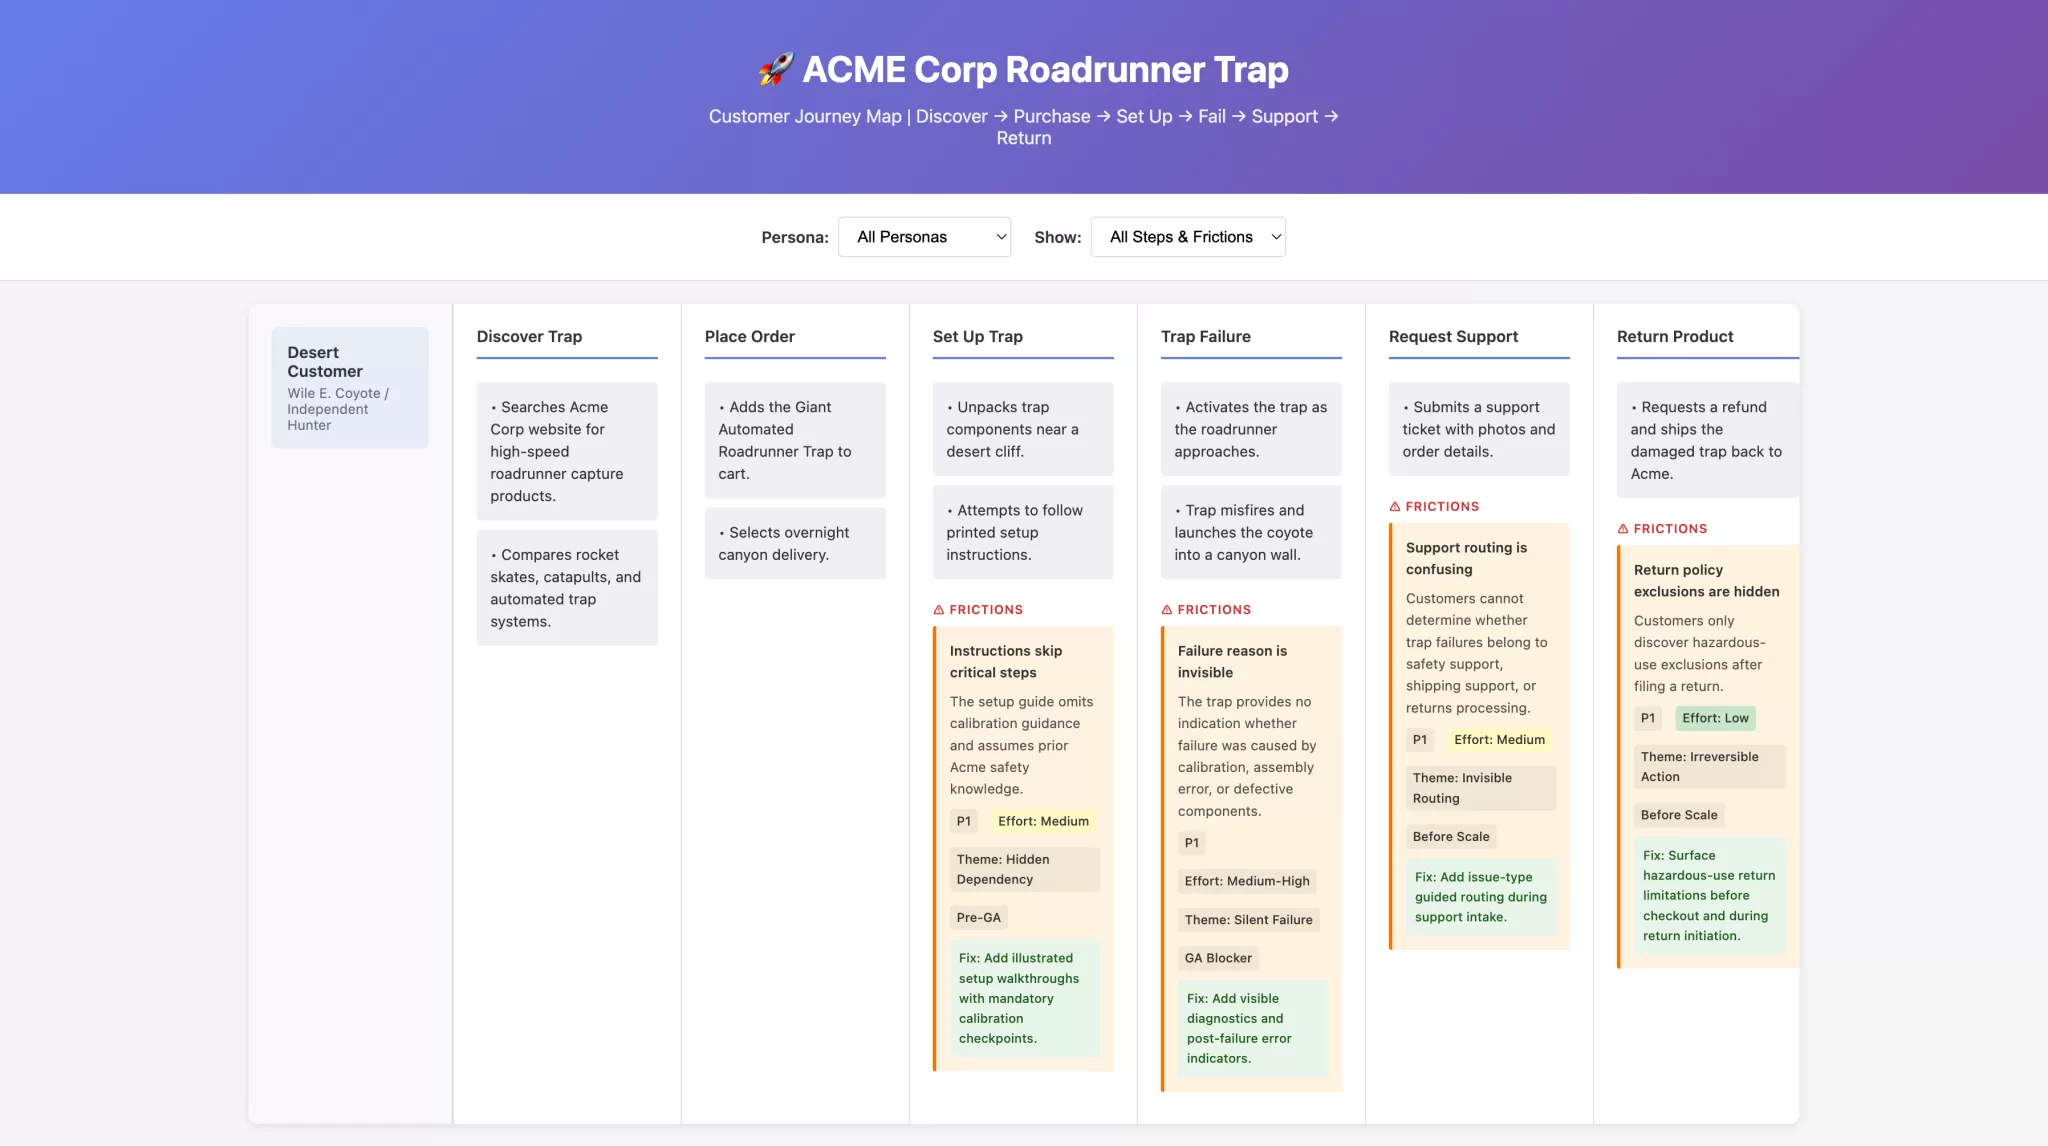
- Map generation — Claude synthesizes the scoped sources into the journey-map schema: personas as rows, stages as columns, cells carrying actions, touchpoints, thoughts and feelings, challenges, pain points, and opportunities.
- Interactive editor — The generated map is a draft, not a deliverable. Teams add, edit, and delete stages and personas directly on the canvas, drag to reorder, and color-code pain and opportunity severity.
- Library and versioning — Saved maps carry metadata — source count, persona count, dates — with v1/v2 version tracking and JSON or markdown export for engineering handoff.
Tradeoffs: What V1 deliberately did not include: a template library, real-time collaborative scoping, Figma export — and no automated Zendesk or Slack integration; sources enter by paste, upload, or link. The bet was to ship the core loop — ingest, scope, generate, edit — and let the first weeks of real use pick the roadmap, rather than guessing at integrations before anyone had used the tool in anger.
Human judgment stayed in the loop
JEM was designed to accelerate synthesis, not decide what the team should believe. People choose and scope the sources, steer the map through the guided conversation, inspect the generated draft, edit the canvas, and decide which version is ready for handoff. The AI produces a structured starting point; the team remains responsible for interpretation and prioritization.
Results
| Metric | Detail |
|---|---|
| 10–15 hrs estimated time avoided per discovery cycle | Hand synthesis of docs, transcripts, and tickets → a structured draft in one working session; not a controlled time study |
| 10 fixes shipped in week one | Launched to an internal test environment, used immediately, iterated immediately |
| 8 weeks concept to engineering handoff and initial internal use | Product architecture, data model, and UI — designed, built, and verified in the internal test environment |
Lessons
- The first data model was designed in the abstract — and it showed. The schema only became right after it was run against a real discovery project mid-build, which forced changes a whiteboard session never would have surfaced. Next time the schema gets designed against a live project from day one.
- Scoping as a conversation beat scoping as a form. The refinement buttons are the design insight I would reuse anywhere: constraining how people steer an AI is interface design, and it is what separates a usable AI tool from a prompt box with instructions.
- Ten fixes in week one is the metric I trust most. A tool that surfaces ten real issues in its first week is a tool people are actually using. Adoption shows up as friction reports, not as praise.
FAQ
Did you build JEM alone? No. I conceived the product, designed every interface, and defined the data model and source taxonomy; Tovuti's lead engineer implemented it and the principal engineer reviewed the infrastructure. I own the design and the product thinking — the production code was a collaboration, and pretending otherwise would misrepresent both.
Why the Claude API instead of a cheaper model? Two reasons: multi-source synthesis quality, and streaming. The scoping conversation is the product — if the model reasons poorly across mixed source types, the generated map is wrong in ways users cannot easily see, and if responses do not stream, the conversation stops feeling like one.